Category: Entra ID

  • Moving from Entra Connect Sync to Cloud Sync: what you actually need to know before you touch anything

    Let’s start with the headline, because it changes the tone of the rest of this post: Microsoft confirmed in April 2026 that Entra Connect Sync is being retired. Cloud Sync becomes the default sync engine, and tenant notifications have been rolling out in phased waves since July 2026, based on which features each environment actually needs from Cloud Sync before it’s safe to move.

    Worth being precise about what that means, because there’s a fair amount of noise around it. It isn’t a single hard cut-off for everyone — Microsoft’s own guidance is that you’re not required to migrate until the features you depend on are supported in Cloud Sync, and you can request an exception if you’re genuinely not ready. But it is a retirement, not a suggestion. If you’re still running Connect Sync, you’re already somewhere in that queue, whether or not the notification has landed in your tenant yet.

    Don’t confuse this with the other Connect Sync deadline doing the rounds — the mandatory upgrade to version 2.5.79.0 or later by 30 September 2026, after which synchronisation stops working entirely if you haven’t updated. That’s a security hardening requirement, not the retirement itself. They’re two different clocks. If you’re behind on patching, sort that first before you even start thinking about migration timelines.

    I’ve sat through enough of these migrations now to know the pattern: someone reads a “Cloud Sync is the future” blog post, spins up an agent in a test tenant over lunch, and declares the project basically done. Then Hybrid Azure AD Join breaks, or a group with 60,000 members refuses to sync, and suddenly it’s a very different conversation with the customer.

    So this post is the version I wish someone had handed me before my first Cloud Sync migration: what’s actually happening with the retirement, what Cloud Sync changes, what to check before you start, and where people trip up.

    Why bother moving at all?

    Connect Sync has done its job well for a decade. And now, with a retirement date attached to it rather than just a lack of new features, “increasingly a job nobody wants to own” becomes “a job that’s going away regardless.” That changes how you prioritise this internally — it’s no longer purely a modernisation project you can defer indefinitely.

    It’s a Windows server, sat on-prem, with a sync engine, a database, and a scheduler that somebody has to patch, back up, and babysit. When it falls over at 2am, it’s your problem, and usually it’s your problem alone, because most environments only run one.

    Cloud Sync flips that around. The configuration lives in Entra ID and you manage it from the Entra Admin Centre. What’s left on-prem is a lightweight provisioning agent — genuinely lightweight, not “lightweight” in the way vendors usually mean it.

    The bit I actually care about as a consultant: you can run several active agents at once. Connect Sync gives you an active/passive pair if you’re disciplined about it. Cloud Sync gives you proper active/active, so one agent falling over doesn’t take sync down at all. For anyone who’s been paged because the one Connect Sync box died overnight, that alone is worth the migration.

    Other things worth knowing:

    • Agents update themselves. No more scheduling patch windows for the sync server.
    • Disconnected forests are supported natively — no VPNs or trust relationships needed just to sync identities.
    • New Microsoft sync features land here first, sometimes exclusively.
    • The infrastructure footprint shrinks considerably — no SQL Server (or ADAM/AD LDS) to maintain.

    None of this means Connect Sync is bad. It means Microsoft has stopped investing in it the way they invest in Cloud Sync, and that gap will only widen.

    Before you touch a single agent: check whether you actually can move

    This is the step people skip, and it’s the one that causes the awkward client calls later.

    Cloud Sync doesn’t do everything Connect Sync does. Not yet, and in some cases maybe not ever. Go through this list honestly before you promise anyone a migration date.

    Scale. Cloud Sync currently tops out at 150,000 objects per AD domain, and groups are capped at 50,000 members. If you’re a large enterprise with sprawling security groups, check your actual numbers — don’t assume you’re fine.

    Hybrid Azure AD Join. This is the one that catches people out most often. Connect Sync supports it. Cloud Sync currently doesn’t. If your organisation still relies on Hybrid Azure AD Join for device management, that’s not a footnote — it’s a blocker, and it needs its own conversation (and likely its own plan, possibly involving Entra Join instead) before Cloud Sync becomes viable for you.

    Custom sync rules. If you’ve got a sync engine full of custom inbound/outbound rules, attribute transforms, and clever filtering that some contractor built five years ago and nobody’s touched since — go and actually read it. Cloud Sync has an attribute-mapping expression builder, and it’s decent for straightforward transforms. It is not the Connect Sync rules engine. If your rules are doing anything genuinely complex, expect rework, not a like-for-like port.

    Forest design. Cloud Sync handles single forests, multiple connected forests, and multiple disconnected forests. Fine for most setups. If you’ve got a complicated cross-forest arrangement, go through Microsoft’s feature comparison line by line rather than assuming it’ll just work — cross-forest is exactly where the edge cases live.

    If any of this rings alarm bells, that’s not a reason to abandon the idea. It’s a reason to scope properly before you start, rather than discovering the gap mid-migration.

    Prerequisites: the boring bit that saves you later

    Document what you’ve actually got. Not what you think you’ve got — what’s actually configured. OU filtering, which object types sync, Password Hash Sync settings, PTA and Seamless SSO config, every custom rule, directory extensions in use, group writeback, and anything tied to Exchange hybrid. I promise you this document will matter more during troubleshooting than during planning.

    Export your Connect Sync configuration. Use the built-in import/export settings feature before you change anything. It’s a five-minute job and it’s your safety net if something goes sideways.

    Check your authentication story separately from sync. This is genuinely good news, and it’s worth saying plainly: PTA and Seamless SSO are configured independently of the sync engine, so they keep working through the migration. Authentication is not the thing that breaks here. Sync scoping and attribute behaviour are.

    Get the provisioning agents deployed. Install them on supported servers ahead of time, and deploy at least two. This isn’t gold-plating — a single agent just recreates the single-point-of-failure problem you were trying to get away from.

    How to actually run the migration

    There’s one rule that matters more than any other: never sync the same objects through both engines at once. Microsoft is explicit that this isn’t supported, and I’ve seen what happens when someone tries it anyway — duplicate writes, confused attribute states, and a support case that takes far longer to unpick than the migration itself would have taken done properly.

    The way round this is scoping by OU. Cloud Sync takes ownership of specific OUs while Connect Sync keeps managing the rest, and you move the boundary a bit at a time.

    Phase 1 — Pilot. Pick a small OU: test users, test groups, non-production service accounts. Nobody important. Validate attribute flow, password sync, group membership, and general provisioning behaviour. Cloud Sync’s on-demand provisioning is genuinely useful here — you can trigger sync for one specific user and watch exactly what happens, rather than waiting for a scheduled run and hoping.

    Phase 2 — Configure Cloud Sync properly. Set up forest connectivity, OU scoping, attribute mappings, and Password Hash Sync. Don’t rush this bit — test it thoroughly before you let it anywhere near a production OU.

    Phase 3 — Put Connect Sync into staging mode. This is the checkpoint that matters most. Staging mode lets Cloud Sync take over as the active engine while Connect Sync stays configured and ready as a rollback path. Before flipping anything live, check your object counts match, provisioning is behaving, group memberships are correct, and password sync is actually working — not just “looks fine at a glance.”

    Phase 4 — Widen the net. Move more OUs across once the pilot’s proven itself. Validate after every phase, watch sync health properly, and resist the temptation to move everything at once because the pilot went smoothly. It always looks easy until the OU with the awkward legacy group turns up.

    Phase 5 — Cut over fully. Once everything’s migrated, check sync health, confirm provisioning, verify authentication is still solid, and go through the provisioning logs properly. Only decommission the old Connect Sync infrastructure once you’re genuinely confident, not just hopeful.

    Where people actually get burned

    Splitting related objects across two engines. This is the mistake I see most often in staged migrations — users move to Cloud Sync while their groups stay on Connect Sync, or vice versa. The two engines don’t share an understanding of object relationships, so group memberships start behaving oddly in ways that are genuinely painful to debug afterwards. Move related objects together. Users and their groups go in the same phase.

    Assuming feature parity that doesn’t exist. Organisations that have been running Connect Sync for years have usually accumulated a fair bit of custom logic nobody fully remembers building. Go through your custom attribute flows, sync rules, device sync requirements, and group writeback dependencies properly before you commit to a date. Not everything has a direct equivalent in Cloud Sync, and finding that out mid-migration is a bad time to find it out.

    Testing the pilot too lightly. “It provisioned a test user” is not a pilot. A proper pilot covers password changes, group membership updates, attribute updates, anything Exchange-related, and joiner/mover/leaver scenarios. Those last three are where the real-world mess lives — a user changing department, a contractor’s account being disabled, someone getting rehired eight months later. If your pilot doesn’t touch those, it hasn’t actually told you much.

    Is it worth doing?

    Yes, generally — but on a timeline that matches your actual complexity, not the one a vendor slide deck implies.

    If you’re running straightforward user and group sync, this is a genuinely quick win, and honestly one of the more satisfying migrations to run: less infrastructure, less patching, less 2am paging.

    If you’ve got Hybrid Azure AD Join dependencies, heavy custom sync rules, or a large or complex environment, take the time upfront. Do the readiness assessment properly. Run a pilot that actually tests the edge cases, not just the happy path.

    Move in phases, validate at every step, and keep Connect Sync as your safety net until you’re actually confident — not just optimistic. That’s the difference between a migration that goes quietly and one that ends up as a war story at the next conference.
  • Deploying Microsoft Intune Endpoint Privilege Management: What Actually Works

    Most organisations I work with have been chasing least privilege for years. Strip out local admin rights, shrink the attack surface, limit what a compromised account can do. All good instincts.

    The trouble is what happens on Monday morning when someone genuinely needs to install a printer driver or run an update that insists on admin rights. That’s the gap EPM was built to close.

    Microsoft Intune Endpoint Privilege Management (EPM), part of the Intune Suite and now part of Microsoft 365 E5, lets standard users run specific approved things with elevated rights—on demand, for that one task, without ever making them a local admin. No more, no less.

    This is the deployment playbook I use with clients: how EPM actually works under the hood, how to roll it out without a support desk meltdown, and the configuration choices that separate a good deployment from one that just moves the risk around.

    What EPM actually does

    EPM elevates specific applications, scripts, installers and processes. The user stays a standard user throughout. That distinction matters more than it sounds — you’re not granting a person more power; you’re granting a process more power, for as long as it needs it.

    Under the hood, EPM policies decide:

    • Which applications are allowed to elevate
    • Who is allowed to trigger that elevation
    • Whether the user has to explain why
    • Whether someone else has to approve it first
    • Whether it happens automatically or on request
    • What gets logged when it does

    Get this right, and you’ve got Zero Trust in practice rather than Zero Trust as a slide in a deck.

    The architecture, briefly

    Three pieces do the work:

    The EPM service sits in the cloud, bolted onto Intune. It manages policy and reporting.

    The Intune Management Extension (IME) is the bit already running on your endpoints that pulls those policies down.

    The EPM client components sit on the device itself, evaluating each elevation request as it happens.

    When someone launches something that needs admin rights, EPM checks it against your rules, decides whether to allow it, runs that one process elevated if approved, and ships the audit trail straight back to Intune. The user’s session itself never changes. Only the process does.

    Licensing — check this before you get excited

    EPM needs one of the following sitting on every user you want covered:

    • Microsoft 365 E5
    • Microsoft Intune Suite
    • The Intune EPM add-on

    It works on Windows 10 and 11, on Entra-joined or Entra hybrid-joined devices. Devices need to be enrolled in Intune with the Management Extension installed — if that’s not already ticking along on your estate, sort that first.

    I’ve seen more than one EPM pilot stall for a fortnight because nobody checked licensing coverage until after the policies were built. Do this bit first.

    Plan before you configure anything

    Here’s the mistake I see most often: someone gets excited about EPM, builds a few elevation rules based on gut feel, and rolls it out. Three weeks later, the helpdesk is drowning in tickets because nobody actually knew what needed admin rights in the first place.

    Before touching a policy, find out what’s actually elevating today. Look at:

    • Line-of-business applications with dodgy installers
    • Legacy software that’s never been rewritten to behave
    • Update mechanisms that insist on admin rights for no good reason
    • Device management and monitoring tools
    • Developer toolchains
    • Anything bespoke and internal

    Microsoft Defender for Endpoint and advanced hunting queries are genuinely useful here — they’ll show you real elevation attempts rather than what you assume is happening. Your existing software deployment reports are worth a look too.

    This discovery phase is unglamorous, and it’s the single biggest predictor of whether the rollout goes smoothly.

    Roll it out in phases — don’t be a hero

    A big-bang EPM deployment across the whole estate is asking for trouble. I always recommend three phases.

    Phase 1 — Discovery. A small pilot group: IT admins, security team, application owners, a few power users. Use them to work out what your elevation scenarios actually look like before anyone else sees a prompt.

    Phase 2 — Controlled pilot. Push EPM to a limited slice of real production users. Watch the user experience closely, check application compatibility, make sure reporting and audit events are landing where you expect.

    Phase 3 — Enterprise rollout. Expand in waves — by department, device type, region, risk profile, whatever makes sense for your organisation. Waves, not one big switch.

    Configuring EPM

    Step 1 — Turn it on. In the Intune admin centre, go to Endpoint Security → Endpoint Privilege Management, enable it, and assign the policy to the device groups you actually mean to target.

    Step 2 — Build your elevation settings policy. This is where you decide how elevation feels for the user. There are four flavours:

    Automatic elevation — the app elevates automatically, with no prompt. Fine for trusted business apps and standardised, well-understood tools. I wouldn’t reach for this outside of software you genuinely trust without question.

    User confirmed elevation — a prompt the user has to accept. Good for the odd admin task and medium-risk tools.

    User justification — the user has to type a reason before it elevates. This is where I’d put anything remotely sensitive — administrative utilities, security tooling, that sort of thing. The justification text is more useful than people expect when you’re investigating something later.

    Approval required — someone else has to say yes first. Reserve this for your genuinely high-risk admin tools and privileged maintenance work. It’s friction, and friction is the point.

    Elevation rules — how you identify what’s allowed to run

    Three ways to match an application, each with a real trade-off.

    File hash. The most secure option, full stop. Nothing gets through unless it’s the exact binary you approved. The catch is maintenance — every update means a new hash, so this works best for tools that don’t change often, like dedicated security utilities.

    File certificate. Matches on the publisher’s signing certificate rather than the exact file. Much less maintenance, and it survives normal software updates without you lifting a finger. The trade-off is you’re trusting the publisher more broadly, so this is best kept for Microsoft software and vendors you genuinely trust.

    File path. Matches on where the file lives. It’s the easiest to set up and, frankly, the one I’d avoid wherever possible — a folder path is trivial to abuse if an attacker can drop something into it. Use this only when hash or certificate matching genuinely isn’t an option.

    Configuration choices that actually matter

    1. Remove local admin rights first

    EPM isn’t meant to sit alongside widespread local admin access — it’s meant to replace it. If you deploy EPM but leave half your estate with standing admin rights, you’ve added a control without removing the risk it was meant to address. Pull permanent local admin memberships where you can, bring in proper privileged access management, and use EPM to handle the genuine exceptions.

    2. Lean on certificate rules

    For most enterprise software, certificate-based rules give you the best balance of security and sanity. Avoid broad path-based rules altogether, and think twice before going hash-only on anything that updates frequently — you’ll be maintaining that rule forever.

    3. Make people justify PowerShell, CMD, and friends

    PowerShell, Command Prompt, Registry Editor, Device Manager, MMC snap-ins — require justification and full audit logging on all of them. When something goes wrong later, having a written reason attached to every elevation is genuinely useful, not just a box-ticking exercise.

    4. No wildcard rules. Ever.

    Don’t allow entire folders or generic paths to elevate. C:\Temp\*, Downloads folders, user profile directories — these are exactly where an attacker would drop a payload, and a wildcard rule hands them the keys. If you find yourself writing a wildcard to save time, that’s the moment to stop and find the specific rule instead.

    5. Wire it into Microsoft Defender for Endpoint

    Defender gives you visibility into elevated process execution, incidents and investigations that EPM alone won’t show you. Your security team should correlate EPM events with endpoint telemetry, not treat them as two separate data sets.

    6. Use RBAC properly

    Don’t let one team own policy creation, application approval and reporting all at once. Split those responsibilities through Intune’s role-based access control. It’s a small thing that meaningfully reduces the risk of someone quietly approving their own elevation request.

    7. Time-limit your approvals

    If you use approval workflows, require a business reason, cap how long the approval lasts, and review them regularly. Elevation that never expires isn’t really elevation — it’s just admin rights with extra steps.

    8. Audit everything, properly

    Capture elevation requests, approvals, justifications, elevated launches and policy matches. Keep that data for as long as your security policy requires. When an incident happens, this data tells you what actually ran and why.

    Keep watching after go-live

    EPM deployments don’t finish at go-live — that’s when the real work starts. Review regularly:

    • Which applications are being elevated most
    • Failed elevation attempts
    • Approval requests coming through
    • What people are writing in the justification field
    • Any device generating unusually high elevation activity

    A sudden spike in elevation activity is worth investigating properly. It might just be a new tool rolling out, or a training gap, but it might also be someone poking around where they shouldn’t be. Treat it as a signal, not noise.

    EPM isn’t the whole story

    EPM meaningfully reduces risk compared with handing out local admin rights, but don’t mistake it for a complete security control. It’s one layer.

    Pair it with Microsoft Defender for Endpoint, Attack Surface Reduction rules, Application Control for Business (the WDAC rebrand), Conditional Access, Privileged Identity Management, security baselines and device compliance policies. Together, that’s a layered defence that actually earns the label Zero Trust rather than just borrowing the phrase.

    Mistakes I see again and again

    • Migrating everyone at once instead of phasing it
    • Leaning too hard on path-based rules because they’re quick
    • Skipping the discovery phase and finding out what needs elevation the hard way
    • Not monitoring elevation events once the policy is live
    • Handing out approval permissions too broadly
    • Letting developers elevate whatever they like, whenever they like
    • Treating EPM as a substitute for proper application control rather than a companion to it

    Fix these early, and the rest of the deployment tends to look after itself.

    My Final thoughts

    Of everything in Intune, EPM is one of the controls I’d genuinely encourage every organisation still running local admin rights to look at seriously. It lets you get rid of standing admin access without users feeling like they’ve been locked out of doing their jobs — which, in my experience, is usually the thing that kills these projects before they start.

    The deployments that go well share the same pattern: proper discovery up front, a phased rollout, sensible governance, and monitoring that doesn’t stop once the project’s marked complete. Pair EPM with Defender for Endpoint, Application Control and your wider Zero Trust controls, and it becomes a genuinely load-bearing part of your endpoint security strategy — not just another policy nobody looks at again.

    If you’re still sitting on widespread local admin rights, EPM is a practical, well-trodden way to start taking that away — without your users noticing much difference to how they work.

  • Microsoft 365 E5 Just Got Considerably More Useful for Endpoint Security

    If you’re running Microsoft 365 E5, go and check your tenant. There’s a good chance you’re now licensed for tools you’ve been meaning to buy for the last two years.

    As of July 2026, Microsoft has folded several premium Intune Suite capabilities directly into E5 licensing, no add-on required. I’ve been doing endpoint security work in this space for a while, and this is the kind of license change that quietly changes project priorities. It’s not flashy, but it matters.

    Microsoft’s own announcement covers the details here and here. This post is my take on what actually matters to the people who have to implement it.

    Why This Actually Matters

    Endpoint management used to mean pushing out policies and calling it a day. That’s not the job any more.

    Security teams are now expected to strip out admin rights, secure a workforce that’s half at home and half in the office, get off ageing certificate infrastructure, and actually see what’s happening across their device estate — usually with the same headcount they had five years ago.

    Microsoft including these capabilities in E5 by default tells you where they think endpoint security sits now: not as a nice-to-have bolt-on, but as core Zero Trust capability. I’d agree with that read.

    What You Actually Get

    Microsoft 365 E5 already included everything in E3. Now it also picks up a set of Intune Suite features that used to need separate licensing.

    Rolled in from the E3 side:

    • Intune Remote Help
    • Intune Advanced Analytics
    • Intune Plan 2
    • Microsoft Tunnel for Mobile Application Management

    New on top for E5 customers specifically:

    • Endpoint Privilege Management (EPM)
    • Microsoft Cloud PKI
    • Enterprise Application Management (EAM)

    Let’s go through each one, because a bullet list doesn’t tell you why you’d care.

    Endpoint Privilege Management: the one I’d deploy first

    This is the headline feature, and honestly, it’s the one I’d tackle first if I were prioritising a rollout.

    Every environment I’ve worked in has the same story: users get local admin because taking it away breaks something, or generates a wave of helpdesk tickets nobody has time for. And every environment I’ve worked in also knows that standing admin rights are one of the easiest wins for a ransomware operator or anyone else trying to move sideways through a network.

    EPM gives you a middle ground. Users stay standard users day to day. Specific approved applications can run elevated. Elevation can be just-in-time rather than permanent, governed by rules you control, and every elevation event gets logged.

    In practice, that means an engineer doesn’t need full local admin just to run Wireshark or SQL Server Management Studio. You allow those specific tools to elevate, and the rest of the machine stays locked down. It’s the least-privilege principle without the political fight of ripping admin rights away wholesale.

    Microsoft Cloud PKI: retire the certificate server nobody wants to touch

    Every organisation I’ve walked into that still runs on-premises Certificate Authorities is running them for the same handful of reasons: Wi-Fi authentication, VPN authentication, and device or user certificates.

    And every one of those CAs comes with the same baggage — infrastructure to patch and maintain, certificate lifecycles someone has to track manually, high-availability requirements, and the quiet risk of a CA server nobody’s touched a security update on in eighteen months. You know the one.

    Cloud PKI moves certificate issuance, renewal, and revocation into Intune, hosted by Microsoft. For anyone genuinely trying to get off legacy infrastructure rather than just talking about it, this is a real opportunity to switch off that server room CA for good.

    Enterprise Application Management: less time repackaging Win32 apps

    Packaging and maintaining Win32 applications is unglamorous work, and it eats far more admin time than it should.

    Test the update, repackage it, redeploy it, repeat next month. Most endpoint teams have at least one person who spends a disproportionate chunk of their week on exactly this.

    EAM pulls from Microsoft’s own catalogue of pre-packaged, kept-current applications, so a good chunk of that churn disappears. For an organisation managing a few thousand endpoints, that’s not a minor convenience — it’s hours back every week and users getting patched software faster.

    Intune Advanced Analytics: fewer surprises from the helpdesk

    Visibility is still where most endpoint management falls down. You usually find out a device is struggling when the user rings the helpdesk, not before.

    Advanced Analytics gives you device performance, endpoint health, user experience and app reliability data, and Microsoft has recently added near real-time device queries, Multi-Device Query, and AI-assisted analytics through Security Copilot.

    The practical upshot: you can spot a device that’s about to have a bad boot time, or an app that’s crashing across a subset of your estate, before it turns into forty tickets. That’s the difference between reactive firefighting and actually running the environment.

    Intune Remote Help: support without a third-party tool

    Remote support tooling is one of those things everyone has, and almost everyone has bolted on from a third party with its own login, its own audit trail, and its own gaps.

    Remote Help sits inside the Microsoft security stack instead — Entra authentication, role-based access, compliance-aware access, and every session logged and auditable. For hybrid teams, that’s one fewer vendor relationship and one fewer audit trail to reconcile at year end.

    Intune Plan 2: the frontline and specialty device stuff

    If your estate is all corporate Windows laptops, this section won’t excite you much. If you’ve got shared devices, rugged Android handhelds, or Zebra scanners on a warehouse floor, it will.

    Plan 2 covers specialty and shared device management, stronger Android controls, and Zebra firmware update management. Retail, logistics, manufacturing and healthcare environments tend to get the most out of this — it’s the difference between managing frontline devices properly and managing them by exception.

    Microsoft Tunnel for MAM: BYOD without full enrolment

    BYOD is still a genuine headache. Users don’t want their personal phone fully enrolled and managed, and honestly, I don’t blame them.

    Tunnel for MAM gives you per-app VPN access to internal resources without requiring full device enrolment, so corporate data stays protected without Microsoft — or you — needing visibility into someone’s personal photos and apps. It’s a reasonable compromise, and one that tends to get much less pushback from users than full MDM enrolment.

    Security Copilot: still separately licensed, but worth watching

    Security Copilot itself isn’t part of this bundle — that’s a separate licence — but Microsoft keeps deepening the integration with Intune: natural language queries against Intune data, AI-assisted KQL generation, risk scoring for EPM elevation requests, and vulnerability remediation guidance.

    I’d treat this as a direction of travel rather than a reason to buy anything today. Microsoft is clearly building towards AI-assisted administration as a standard part of endpoint management, not a novelty. Worth keeping an eye on, not worth rushing into.

    What This Means If You’re Already on E5

    If you’re already licensed for Microsoft 365 E5, none of this requires a procurement conversation. It requires a deployment plan.

    Realistically, that means:

    • Turning off standing local admin rights via EPM
    • Planning the retirement of your legacy on-premises CA
    • Cutting down repackaging effort with EAM
    • Actually using the visibility Advanced Analytics gives you
    • Consolidating remote support onto Remote Help

    In my experience, a lot of organisations already own tooling they’ve never turned on. This is a good example — Intune Suite used to be viewed as a nice-to-have upsell, and many teams quietly filed it under ‘later’. For a lot of E5 customers, later is now.

    My Final Thoughts

    This is one of the more significant endpoint licensing changes I’ve seen in a while, and it didn’t get nearly enough attention when it landed.

    Bundling EPM, Cloud PKI, EAM, Advanced Analytics, Remote Help and the rest into E5 makes genuinely enterprise-grade endpoint management accessible to organisations that would previously have had to build a business case for every one of these separately.

    If you’re working towards Zero Trust and you’re already on E5, this is worth an afternoon of your time. Go and check what you’re actually entitled to before you plan your next quarter — I’d put money on there being at least one capability in here you’re already paying for and not using.

  • Getting Ready for Microsoft’s Move to Phishing-Resistant MFA by Default

    If you’ve already deployed MFA across your organisation, it’s easy to assume you’re in a good place from a security perspective. A few years ago, that would probably have been true. Today, however, the threat landscape looks very different.

    Microsoft has been steadily raising the security baseline across Microsoft Entra ID and Microsoft 365, and one of the most significant changes is the move towards phishing-resistant authentication becoming the default expectation rather than an advanced security feature.

    Traditional MFA methods such as SMS codes, phone calls, Microsoft Authenticator prompts, and one-time passcodes have undoubtedly improved security. Unfortunately, modern attacks increasingly focus on bypassing these controls through techniques such as adversary-in-the-middle phishing, MFA fatigue, token theft, and session hijacking.

    That’s why organisations are now being encouraged to move beyond simply enabling MFA and towards using authentication methods designed to resist phishing attacks altogether.

    The direction of travel is clear: organisations need authentication methods that are resistant to phishing by design, not just harder for attackers to abuse.

    Why Microsoft is driving this change

    One advantage Microsoft has is visibility. Every day, it processes an enormous volume of authentication requests across Microsoft Entra ID and Microsoft 365, providing valuable insight into how identity-based attacks continue to evolve.

    Despite years of security improvements, password-based attacks are still one of the most common ways attackers gain access to organisations’ environments. What’s more concerning is that modern phishing kits have become sophisticated enough to capture not only usernames and passwords, but also MFA responses in real time.

    This highlights an important reality: while traditional MFA is significantly better than relying on passwords alone, it isn’t immune to attack. Different authentication methods can be targeted in different ways:

    • SMS codes can be intercepted or obtained through social engineering techniques.
    • Voice call verification can be vulnerable to telecom-related attacks and account takeover attempts.
    • Push notifications can be abused through MFA fatigue campaigns, where users are bombarded with prompts until they eventually approve one.
    • One-time passcodes (OTPs) can be captured by phishing proxy services that sit between the user and the legitimate sign-in page.

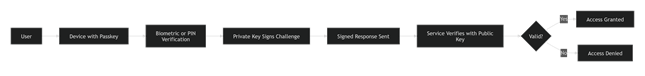
    Phishing-resistant MFA takes a fundamentally different approach. Rather than relying on a code or approval that a user can be tricked into providing. Authentication is bound to the legitimate service being accessed and the device it is being accessed from.

    In practical terms, this means that even if a user is lured to a convincing fake website, the authentication attempt cannot succeed. The security key, passkey, or authentication method recognises that the request is coming from the wrong domain and simply refuses to authenticate. The result is a much stronger defence against modern phishing attacks and one of the key reasons Microsoft is increasingly positioning phishing-resistant authentication as the future of secure sign-ins.

    The Three Main Options for Phishing-Resistant Authentication

    When organisations start exploring phishing-resistant authentication, they typically encounter three technologies that are now widely recognised as the leading options: passkeys, FIDO2 security keys, and Windows Hello for Business.

    While each works slightly differently, they all share a common goal: replacing credentials that can be stolen, intercepted, or tricked out of users with cryptographic authentication methods that are far more difficult for attackers to compromise.

    PasskeysFIDO2 Security KeysWindows Hello
    PasswordlessHardware-backedDevice-bound
    Easy user experienceHighest assuranceNative Windows
    Growing adoptionGreat for privileged usersIdeal for Windows fleets

    Passkeys

    Passkeys are rapidly becoming one of the most talked-about developments in identity security. Rather than relying on a password that a user must remember and enter, passkeys use cryptographic key pairs to verify identity securely behind the scenes.

    From a user perspective, the experience is simple. Authentication can often be completed using a fingerprint, facial recognition, device PIN, or another trusted sign-in method already available on the device.

    One of the biggest advantages is that there is no password to steal and no code to enter into a fake website. Authentication is linked to the genuine service being accessed, making traditional phishing attacks significantly less effective. As a result, passkeys are increasingly being adopted across consumer and enterprise platforms, including Microsoft Entra ID.

    FIDO2 Security Keys

    For organisations seeking a dedicated hardware-based solution, FIDO2 security keys remain among the strongest authentication options available.

    These small physical devices, such as those produced by YubiKey, Feitian, and Token2, allow users to authenticate by inserting or tapping the security key when signing in. The authentication process is backed by cryptographic protections stored within the device itself, removing the need for passwords and reducing the risk of credential theft.

    The appeal of security keys is their simplicity. Users gain a fast and consistent sign-in experience, while security teams benefit from an authentication method that is highly resistant to phishing, credential harvesting, and account takeover attempts.

    Windows Hello for Business

    Windows Hello for Business takes a similar cryptographic approach but integrates it directly into the Windows sign-in experience.

    Instead of entering a password, users authenticate using a PIN, fingerprint, or facial recognition. Behind the scenes, Windows uses a securely stored credential that is tied to both the user and the device.

    This means the authentication process is not dependent on a reusable password that could be captured and reused by an attacker. Because the credential remains protected on the endpoint and is designed to validate against legitimate services, it provides strong protection against many common identity-based attacks while also improving the everyday user experience.

    Preparing for Phishing-Resistant MFA

    Assess your current MFA estate

    Before moving to phishing-resistant authentication, you need to start by understanding what you already have. This gives you a realistic view of where risk exists and where change will have the biggest impact.

    Useful questions include:

    • Which MFA methods are currently in use?
    • How many users still rely on SMS authentication?
    • Are voice calls still enabled for verification?
    • How many users have Microsoft Authenticator configured?
    • Are privileged accounts already using stronger authentication methods?
    • Are break-glass accounts properly secured?

    Microsoft Entra reporting can help identify the authentication methods users have registered. Pay particular attention to Global Administrators, Privileged Role Administrators, Security Administrators, Helpdesk Administrators, and executive leadership teams. These groups should be prioritised first.

    Review your Conditional Access policies

    Conditional Access will be central to enforcing stronger authentication requirements. The key is to move beyond simply asking whether MFA was used and start asking which type of MFA was used.

    Authentication Strengths in Microsoft Entra ID are especially useful here because they allow organisations to require specific phishing-resistant methods, such as FIDO2 security keys, Windows Hello for Business, or passkey authentication.

    This gives you a practical way to phase in the transition rather than forcing a disruptive, organisation-wide change overnight.

    Start with administrators

    Privileged identities should be the first priority. They are high-value targets, and securing them early delivers immediate risk reduction while giving IT and support teams experience with the new authentication methods.

    A sensible rollout path could look like this:

    • Enable phishing-resistant MFA for Global Administrators.
    • Extend the requirement to all privileged roles.
    • Roll it out to IT staff.
    • Expand to high-risk users.
    • Move gradually to the wider employee population.

    This staged approach keeps the rollout manageable while still making progress.

    Prepare your end users

    The technology is only one part of the change. Users need to understand why authentication is changing, what passkeys are, how Windows Hello for Business works, how security keys are used, and what they should do if a device is lost or replaced.

    Good communication should include awareness messaging, simple user guides, short training videos, self-service registration instructions, and clear support escalation paths.

    A better user experience is possible: once people are familiar with the process, phishing-resistant authentication can often feel easier and smoother than traditional MFA.

    Validate device readiness

    A successful rollout depends on knowing whether your devices are ready. Review Windows versions, Intune management status, TPM availability, biometric hardware support, and mobile device readiness.

    For Windows Hello for Business, confirm endpoints meet Microsoft’s recommended hardware and configuration requirements. For passkeys, check support across the mobile platforms your users rely on.

    Develop a recovery strategy

    Recovery is one of the most important — and most overlooked — parts of a phishing-resistant authentication programme. Strong authentication is only successful if users can recover safely when something goes wrong.

    Plan for common scenarios such as lost security keys, replaced mobile devices, damaged laptops, and emergency access requirements.

    Good practice includes registering multiple authentication methods, issuing backup security keys for privileged users, maintaining monitored break-glass accounts, and documenting recovery procedures. A strong recovery process prevents security improvements from becoming operational blockers.

    Monitor adoption and usage

    Migration should be measured continuously. Track authentication method registrations, passkey adoption, FIDO2 usage, authentication failures, Conditional Access policy impact, and helpdesk ticket volumes.

    Microsoft Entra reporting and log analytics can help highlight adoption trends and identify where users may need extra support.